Text Analysis APIs
64 text analysis APIs for translation, sentiment and text processing, best documented first.
Google Cloud Natural
Text AnalysisNatural language understanding technology, including sentiment, entity and syntax analysis
LanguageTool
Text AnalysisStyle and Grammar Checker for 25+ Languages
Tisane
Text AnalysisText Analytics with focus on detection of abusive content and law enforcement applications
LibreTranslate
Text AnalysisTranslation tool with 17 available languages

Asynchronous Speech-To-Text API Documentation
Text AnalysisRev.ai provides quality speech-text recognition via a RESTful API. All public methods and objects are documented here for developer reference. For a real-time speech to text solution, use Rev.ai's [Streaming API](/docs/streaming). # Base Endpoint The base url for this version of the API is > `https://api.rev.ai/speechtotext/v1` All endpoints described in this documentation are relative to this base url. # Quick Start Follow the [getting started checklist](https://www.rev.ai/getting_started) ## Get your Access Token You can generate your [access token](#section/Authentication/Access-Token) on the [settings page](https://www.rev.ai/access_token) of your account. This access token only needs to be generated once and never expires. You can re-generate your token, however this will invalidate the previous token. ## Submit a File To submit an audio file for transcription to Rev.ai: ``` curl -X POST "https://api.rev.ai/speechtotext/v1/jobs" -H "Authorization: Bearer $REV_ACCESS_TOKEN" -H "Content-Type: application/json" -d "{\"media_url\":\"https://www.rev.ai/FTC_Sample_1.mp3\",\"metadata\":\"This is a sample submit jobs option\"}" ``` You’ll receive a response like this: ~~~ { "id": "Umx5c6F7pH7r", "created_on": "2018-09-15T05:14:38.13", "name": "sample.mp3", "metadata": "This is a sample submit jobs option for multipart", "status": "in_progress" } ~~~ The `id` (in this case `Umx5c6F7pH7r`) will allow you to retrieve your transcript. ## Get Your Transcript Once a transcription job's `status` becomes `transcribed`, you can retrieve the transcript in JSON format by running: ``` curl -X GET "https://api.rev.ai/speechtotext/v1/jobs/{id}/transcript" -H "Authorization: Bearer $REV_ACCESS_TOKEN" -H "Accept: application/vnd.rev.transcript.v1.0+json" ``` Alternatively you can get the plain text version by running: ``` curl -X GET "https://api.rev.ai/speechtotext/v1/jobs/{id}/transcript" -H "Authorization: Bearer $REV_ACCESS_TOKEN" -H "Accept: text/plain" ``` You can poll for the `status` of your job by querying for the job periodically: ``` curl -X GET https://api.rev.ai/speechtotext/v1/jobs/{id} -H "Authorization: Bearer $REV_ACCESS_TOKEN" ``` **Note:** Polling is NOT recommended in a production server. Rather, use [webhooks](#section/Webhooks) to asynchronously receive notifications once the transcription job completes If you have any further questions, contact us at <[email protected]> # Submitting Files Two `POST` request formats can be used to submit a file: `application/json` or `multipart/form-data`. ## JSON This is the preferred method of file submission. Uses the `media_url` property to provide a direct download URL to the Rev.ai server. This method supports the use of pre-signed URLs. Links to videos hosted on platforms like Youtube are not valid because they are not direct download links. **Important note on presigned URLs:** Signed URLs usually have an expiration time which is configurable. To ensure the Rev.ai server can access the link, make sure the expiration time is set to 2 hours or more. In the event you plan on resending the same file, make sure to generate a new presigned URL. ## FormData Used to send a local file to the Rev.ai server. This allows the customer to send the file directly from the host machine. Certain limits apply to this format, see the [Async API Limits section](#section/Async-API-Limits) for more detals. # Turnaround Time and Chunking Often, especially for shorter files, your transcript will be ready in 5 minutes or less. It generally takes no longer than 15 minutes to return longer audios. If you require faster turn around time please contact <[email protected]> Chunking is the act of breaking audio files into smaller segments. Rev.ai uses this method to decrease turnaround time of audios greater than 3 minutes in length. # Webhooks If the optional `callback_url` is provided, the API will make an HTTP POST request to the `callback_url` with the following request body when the job either completes successfull
Detect Language
Text AnalysisDetects text language
ELI
Text AnalysisNatural Language Processing Tools for Thai Language

Handwrytten API
Text AnalysisThis is the Handwrytten API for sending cards written in the handwriting of your choice. Using this api, you can send cards to users. You can also customize cards with logos, which can be saved and then used like any other card in the system. For a "sandbox" account, please contact [email protected] To move from credit card per-transaction to monthly invoicing, also contact us. [https://www.handwrytten.com](https://www.handwrytten.com)
MotaWord API
Text AnalysisUse MotaWord API to post and track your translation projects.
Word Associations API
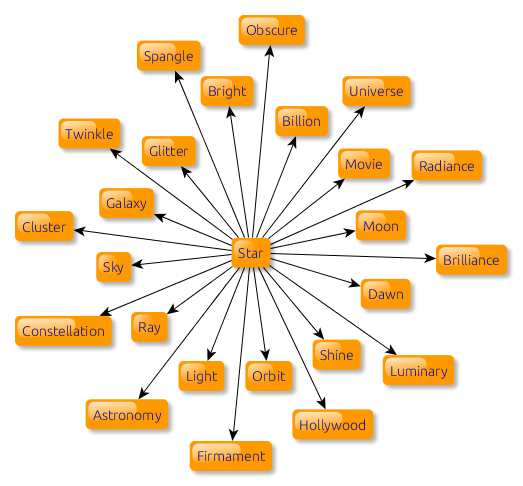
Text AnalysisThe Word Associations Network API allows developers to embed the ability to find associations for a word or phrase into their mobile apps or web services. Words are grouped by semantics, meaning, and psychological perception. The Word Associations Network API currently supports English, French, Spanish, German, Italian, Portuguese, and Russian vocabulary. Please [register and subscribe](https://api.wordassociations.net/subscriptions/) to one of available tariff plans to get a valid API key.
apilayer languagelayer
Text AnalysisLanguage Detection JSON API supporting 173 languages
eidosSpeech
Text AnalysisFree text-to-speech API with 1,200+ neural voices in 75+ languages
GeoScore
Text AnalysisScore content for AI search citation readiness with a 0-100 GEO score and 8 structural metrics
Langbly
Text AnalysisContext-aware text translation and language detection for 100+ languages
Lecto Translation
Text AnalysisTranslation API with free tier and reasonable prices
ToHuman
Text AnalysisRewrite AI-assisted drafts into natural, human-sounding text that reads like you wrote it
Car Registration API
Text AnalysisCar Registration API, An API that retrieves car information from its numberplate in many countries worldwide, uncluding the USA, UK, India, Australia and most of Europe. A username and password is required to access the API, which can be obtained from www.carregistrationapi.com - Use https://www.regcheck.org.uk/api/json.aspx/ as the root of all API calls.

Football Prediction API
Text AnalysisThe Football Prediction API allows developers to get predictions for upcoming football (soccer) matches, results for past matches, and performance monitoring for statistical models.

Historische Daten
Text AnalysisAbfrage von Wetterdaten aus der Vergangenheit. Der maximale Abfragezeitraum beträgt 366 Tage (1 Jahr).
IdealSpot GeoData
Text AnalysisHyperlocal Demographics, Vehicle Traffic, Economic, Market Signals, and More. Use this API to request IdealSpot hyperlocal geospatial market insight and geometry data. ## Detailed Description Use this API as your **local economy microscope** by querying [IdealSpot](https://www.idealspot.com) hyperlocal market insight and geometry data. We offer the most precise, extensive, and frequently-updated local market data in the US. Our data is available across the entire US and can be queried at geographic scales ranging from the micro (Census block) through the macro (nation). Better data and analysis leads to a better understanding of local market opportunities and risks. Integrate with your commercial real estate and marketing applications, machine learning workflows, and other investment analytics. Our goal is to offer the most complete snapshot of the geographically distributed consumer and retail economy. We start with the fundamentals of consumers and business establishments. To connect retailers with consumers, we provide mobility data like vehicle traffic and mobile device data. To describe consumer intent, we provide geolocated digital marketing data. We believe that accurate capital allocation through reliable local market data is foundational to creating robust, healthy, and livable communities for all. We hope you and your clients find tremendous value in this service. ## Features Query data and GeoJSON geometries at these scales for any US latitude and longitude: * Rings (0.5 km+) * Drive time (1-60 minutes) * Bike time (3-60 minutes) * Walk time (5-60 minutes) * Public transit time (5-60 minutes) * Administrative region (US, states, core-based statistical areas, counties, Census-designated places, Census tracts, zipcodes, Census block groups, opportunity zones) | Data Feature | Description | | ------- | ------------------------------| | Demographics, Housing, Spending | *Updated Quarterly*. Current and historical market data including population, spending, and housing. Vendor (PopStats) is relied upon by Walgreens, Ulta Beauty, Blackstone, etc | | Labor, Business Establishments, Economic Conditions | *Updated Quarterly*. Traditional market data including workforce, business establishment counts, and economic conditions like local GDP, unemployment rates. Vendor (PopStats) is relied upon by Walgreens, Ulta Beauty, Blackstone, etc | | Consumer segmentation | *Updated Annually*. Demographics grouped into narrative-oriented segments. | | Vehicle Traffic | *Updated semi-annually*. Gold standard in vehicle traffic data from INRIX. Counts by day of week, time of day and side of street. | | Rings and Travel time polygons | *Estimate in Real-time*. Rings alongside drive time, walk time, bike time, and public transit time polygons. Request as GeoJSON geometries for mapping or use with data queries | | Administrative region polygons | *Updated Annually*. GeoJSON administrative regions from US Census Bureau: block groups, tracts, counties, CBSAs, states, opportunity zones, USPS zipcodes | | Internet Search Volumes | 30 day rolling averages for geolocated advertising potential across 450 business categories from major search engines | | Social Media Interest | 30 day rolling average for geolocated advertising potential across 450 business categories from major social networks | ### Coming Soon! This API powers our local market research platform at [IdealSpot.com](https://www.idealspot.com). The functionality exposed so far is only a portion of our current capabilities. We will be exposing additional API features in time so watch this space! | Data Feature | Description | | ------- | ------------------------------| Mobile device visit counts, points of interest, brands | Fresh point of interest data across 3000+ brands, millions of POI, and historical foot traffic counts using mobile data for those points of interest Origin/destination trips from mobile devices | Map origins and destinations of devices visiting an arbitrary catchment
Language Identification (Prediction)
Text AnalysisAutomatic language detection for any texts. Supports over 150 languages.
Poemist API
Text AnalysisPoemist provides social publishing network that connects amateur poets and serves information about poetry, poets and their poems.

Random Lovecraft
Text AnalysisRandom sentences from the complete works of H.P. Lovecraft. CORS-enabled.
SEDRA IV API
Text AnalysisThe SEDRA API is documented in **OpenAPI format** and uses [ReDoc](https://github.com/Rebilly/ReDoc) for documentation. # Introduction This document describes the JSON API for the Syriac Electronic Data Research Archive (SEDRA). The SEDRA project is a linguistic and literary database of Syriac language and literature focusing on providing electronic access to the corpus of Syriac lexicons with linguistic information added to each entry in those lexicons. The API is a mechanism to provide the linguistic information stored in SEDRA to a broader audience. Additionally there is a XML API for Syriac words which conforms to a prototype Semitic Languages schema which can be found in the XSD file https://sedra.bethmardutho.org/api/semiticLanguages.xsd. # Cross-Origin Resource Sharing This API features Cross-Origin Resource Sharing (CORS) implemented in compliance with the [W3C spec](https://www.w3.org/TR/cors/) and allows cross-domain communication from the browser. All responses have a wildcard same-origin which makes them completely public and accessible to everyone, including any code on any site. # Samples Explaining how to lookup words in the SEDRA API is complex and would clutter the API description. For that reason we have chosen to give the explanation of how to lookup words in its own section. SEDRA can lookup words by the SEDRA word Id. However, it will often be the case that the consumer of information provided by the SEDRA API does not know the SEDRA word Id. It is for that reason that the SEDRA API provides a method to lookup words by the Syriac text. But that process is complicated by the nature of Syriac writing. So the SEDRA API will lookup words for consonantal, partially vocalized, and fully vocalized Syriac text. Using the word Id will provide the most accurate results as the exact word will be returned. Fully vocalized text will provide the next most accurate result. The least accurate results will be returned by partially vocalized and consonantal Syriac words in that order. Following are some samples to help understand how this works. 1. By Word Id [30862](https://sedra.bethmardutho.org/api/word/30862.json) 2. By fully vocalized Syriac word [ܐܰܒܳܪܳܐ](https://sedra.bethmardutho.org/api/word/ܐܰܒܳܪܳܐ.json) 3. By partially vocalized Syriac word [ܐܶܒܪܐ](https://sedra.bethmardutho.org/api/word/ܐܶܒܪܐ.json) 4. By consonantal Syriac word [ܐܒܪܐ](https://sedra.bethmardutho.org/api/word/ܐܒܪܐ.json).